Slug: prompt-to-repeatable-ai-run-sheet
Tags: Practical AI; Prompt Engineering; AI workflow
Meta description: A successful prompt is not yet a reliable process. Build an AI run sheet covering purpose, inputs, constraints, examples, checks and human approval.
You ask an AI tool for something useful. The answer is excellent. A week later you try again and receive something ordinary. A colleague copies your prompt and gets a result that misses the point. The problem may not be the wording alone. You had a successful conversation, but you never captured the process that made it successful.
A prompt is one instruction at one moment. A repeatable workflow also records the purpose, source material, boundaries, examples, quality tests, human decisions and what happens when the answer is uncertain. That fuller record is an AI run sheet.
Why prompt libraries are not enough
Prompt libraries can save time, especially for recurring jobs. But a polished paragraph of instructions often hides assumptions that lived only in the original user’s head. Which audience mattered? Which sources were current? What counted as unacceptable? Which parts were checked manually? Was the output a draft, a decision or merely a set of options?
Generative AI is probabilistic: the same request can produce different answers, and a model or tool may change. OpenAI’s official guidance on evaluations says evals test outputs against specified style and content criteria and are essential when improving applications or changing models. You do not need to be an engineer to use the principle. Define what “good” means before the next answer arrives.
The UK Government’s AI Playbook, published in February 2025, similarly frames safe and effective AI use as more than selecting a tool. It stresses governance, skills, assurance and responsible use. The practical lesson for a small business, creator or team is that useful AI work should be documented at the level of the task.
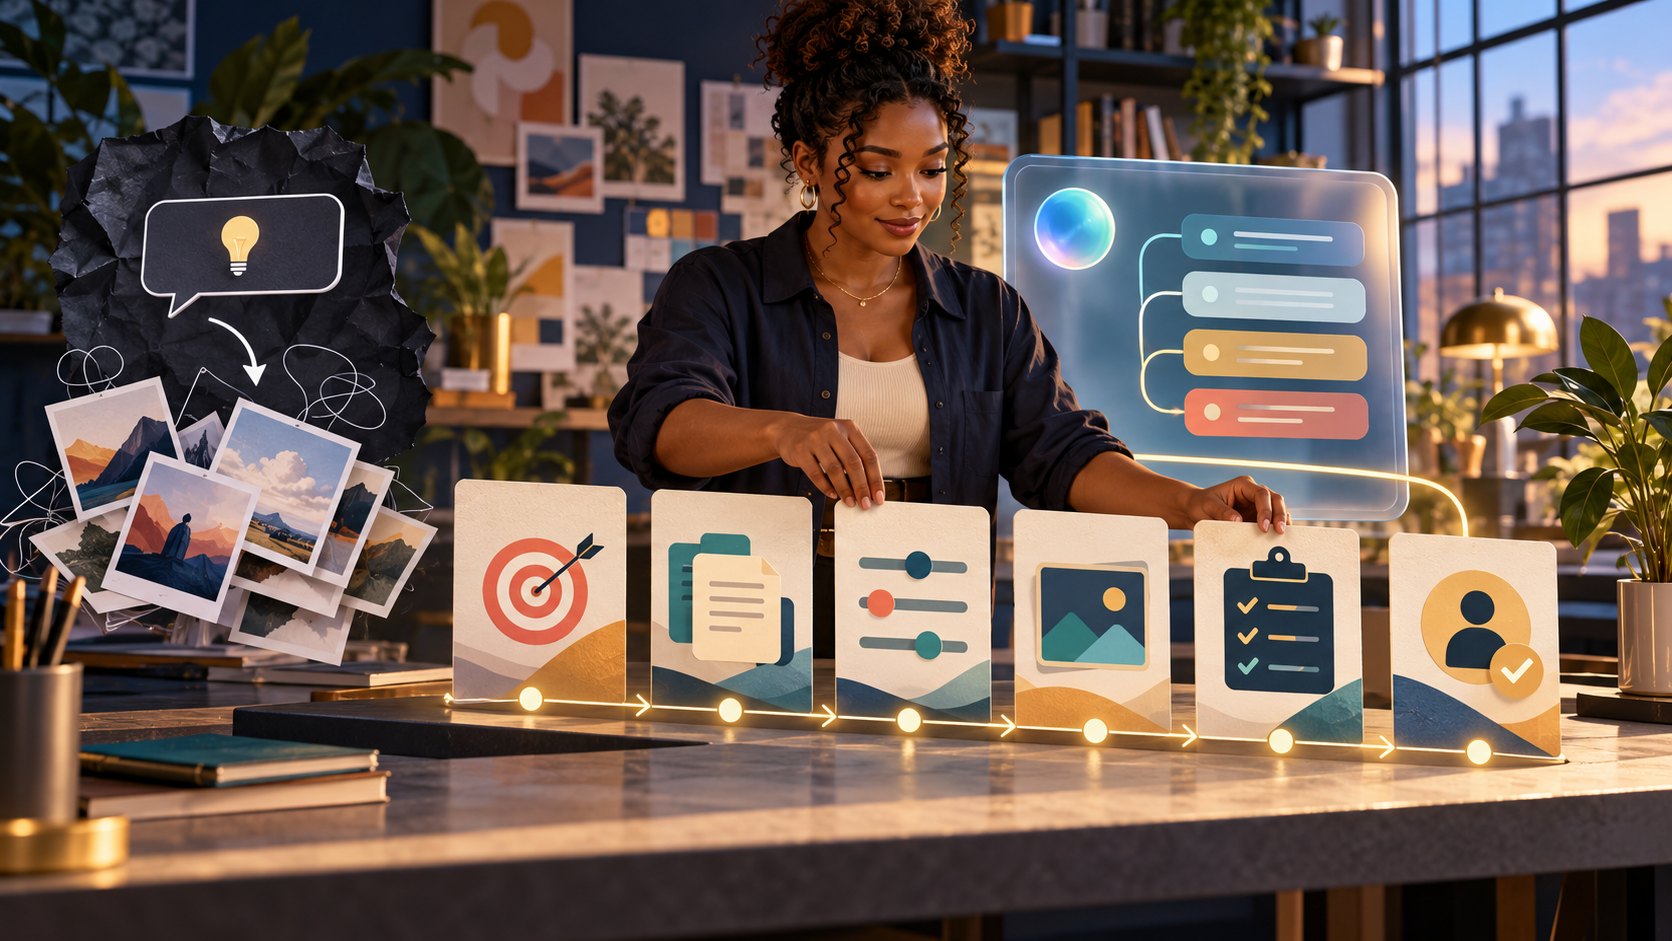
The six-card AI run sheet
Create one short page for each recurring AI task. It can live in a document, project board or internal knowledge base. Use six cards.
1. Purpose: what decision or deliverable is this for?
Name the job in operational language: “Turn a verified product brief into three landing-page options for owner review,” not “write marketing copy”. State who will use the result and what happens next. This prevents the AI from optimising for an attractive answer that cannot enter the real workflow.
Add the risk level. A brainstorming list has a different consequence from a benefits letter, health explanation or hiring recommendation. Higher consequence means stronger evidence, privacy controls and human review.
2. Inputs: what is the AI allowed to rely on?
List the approved sources, their dates and the minimum information required. Separate supplied facts from material the model may retrieve. If current information matters, require fresh sources and direct links. If confidential or personal information must not be entered, say so explicitly.
This card also exposes missing information. A workflow should stop or ask for review when an essential input is absent; it should not quietly invent a plausible substitute.
3. Constraints: what must the output do—and never do?
Record audience, language, length, format, tone, jurisdiction, accessibility needs and prohibited claims. Distinguish hard rules from preferences. “Do not invent statistics” is a hard rule. “Prefer a warm opening” is a preference. Mixing them makes it harder to judge failures.
The NIST Generative AI Profile treats risk management as a continuing activity across design, use and evaluation. Constraints are one way to translate that broad principle into the everyday task: identify the foreseeable harm before generating the output.
4. Example: what does good look like?
Attach one or two approved examples and explain why they are good. Do not rely on imitation alone. Mark the structure, evidence standard, level of detail and voice that should transfer. Also keep one failure example: a confident answer with an unsupported claim may teach the boundary more clearly than another perfect sample.
5. Checks: how will the result be tested?
Turn vague quality into a checklist that can be answered yes, no or not applicable. For example:
- Does every factual claim trace to an approved source?
- Are dates, names, calculations and links accurate?
- Does the answer separate fact, interpretation and speculation?
- Has the output followed the requested structure and British English?
- Could any sentence mislead a reader about evidence, certainty or professional advice?
- Has sensitive information been excluded or handled under the correct policy?
NIST’s framework emphasises mapping, measuring and managing risk rather than relying on confidence. A checklist is not proof of perfection, but it creates a visible test instead of an impression.
6. Human hand-off: who owns the final decision?
Name the reviewer, their authority and the conditions that require escalation. “Human in the loop” is meaningless if the person lacks time, information or permission to reject the result. The Information Commissioner’s Office says meaningful human review should be designed into systems and supported by suitable training, interfaces, authority and escalation routes.
For ordinary creative work, the hand-off may be a quick owner approval. For consequential decisions involving personal data, a more formal process may be required. The ICO’s guidance also connects accountability with documentation: organisations must be able to demonstrate how they meet their obligations, not merely say that a person was present.
Add a small run log
Under the six cards, keep a table or short log for actual runs. Record the date, tool or model, prompt version, source pack, reviewer, result and failure notes. Do not copy sensitive content into the log unnecessarily. The aim is to answer three questions later: what changed, what broke and what improved?
Version the run sheet when a change affects output: a new source, a changed constraint, a better example or a stricter check. Do not overwrite the history so completely that a team cannot explain why older work looks different.
Test cases turn opinions into evidence
Choose five to ten representative tasks and retain them as a small evaluation set. Include easy cases, awkward cases and at least one case the AI should refuse or escalate. Run them after changing the prompt, model or source material. Score the results against the same checklist.
This does not guarantee future performance. It does reveal whether an apparent improvement helps the cases you actually care about. OpenAI’s eval guidance recommends task-specific evaluation because generic impressions do not measure a particular application’s expectations.
Common mistakes
- Saving only the final prompt: the supporting documents, conversation and reviewer edits disappear.
- Testing only happy paths: unusual names, missing fields, conflicting sources and ambiguous requests reveal the real weakness.
- Using confidence as a quality score: fluent language is not verification.
- Making the checklist enormous: reviewers start ticking boxes without thinking. Keep checks tied to meaningful failures.
- Calling approval “oversight”: oversight requires enough context and authority to intervene.
- Ignoring tool changes: rerun representative cases after a significant update.
A reusable starter template
Purpose: [deliverable, audience, next decision]
Inputs: [approved sources, date, missing-data rule]
Constraints: [hard rules, preferences, prohibited content]
Examples: [approved sample and failure sample]
Checks: [five to ten observable criteria]
Human hand-off: [reviewer, authority, escalation trigger]
Run log: [date, version, tool, outcome, learning]
Useful takeaways
- Treat a prompt as one component of a workflow, not the workflow itself.
- Define success before generation so quality is testable.
- Require explicit sources, constraints and missing-data behaviour.
- Give human reviewers enough authority and context to reject or escalate.
- Keep a small, representative test set and rerun it after important changes.
- Version the run sheet so improvement leaves an evidence trail.
A brilliant prompt can be a lucky performance. A run sheet turns the useful parts into shared practice. The goal is not to remove human judgement; it is to place that judgement where the workflow can see, test and improve it.
Discover more from Marychuks.com AI, Psychology, Business & CreativeVerse
Subscribe to get the latest posts sent to your email.