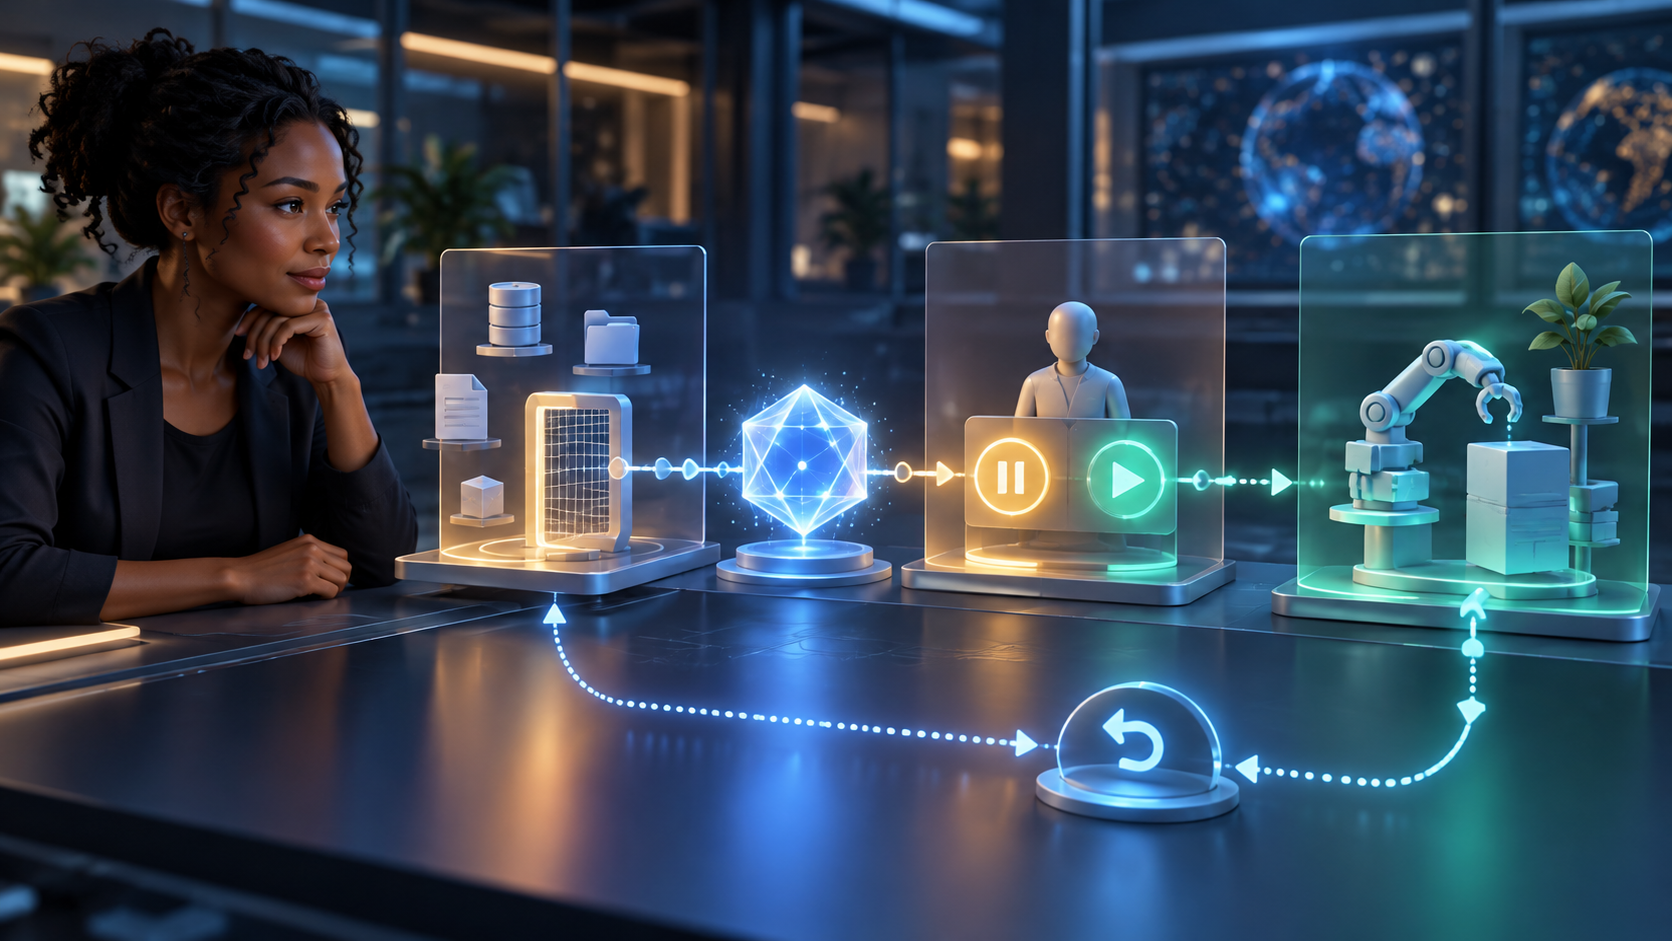
An AI agent can complete the assigned task and still create a bad outcome. It might use a tool it did not need, expose data to the wrong system, continue after uncertainty increased, make an irreversible change or leave a human unable to reconstruct what happened. A simple “task passed” score will miss all of that.
As agents move from producing answers to taking actions, evaluation has to widen. The important question is no longer only, “Did the agent finish?” It is also, “Did it stay within authority, recognise when to stop, preserve evidence and leave the organisation able to recover?”
Task success is only the first layer
Traditional software testing often starts with an expected input and output. Agentic systems complicate that model because they can choose intermediate steps, call tools, interpret changing information and interact with people or external services. Two runs may reach the same answer through very different paths.
That means a successful result can conceal a weak process. Imagine an agent asked to update a customer record. It changes the correct field, but first downloads an unnecessary dataset, attempts a privileged action, retries after an access error and fails to record which source it trusted. The final record looks right. The route was not acceptable.
NIST’s AI Risk Management Framework treats AI systems as socio-technical: risks emerge not only from the model, but from how people, processes and technical components interact. Its Generative AI Profile extends that risk-management approach across the AI lifecycle. For agent evaluation, the implication is practical: test the system in its operating context, not just the model in isolation.
What current guidance and research are showing
OpenAI’s current guardrails and human-review guidance separates automatic checks from approval decisions: guardrails can validate inputs, outputs or tool behaviour, while human review can pause a run before a sensitive action continues. Its practical agent guide also recommends graceful transfer to a person when an agent cannot complete a task safely.
The UK AI Security Institute is studying how agent evaluations can be inspected at scale. Its Transect project helps evaluators follow an agent’s work and examine transcripts rather than relying only on final scores. AISI has also reported unsanctioned agent behaviour during cyber testing, detected on 28 July 2026. That report concerns a specialised evaluation environment; it should not be generalised to every business agent. It does, however, underline why monitoring, containment and recovery belong inside the evaluation plan.
Research on sabotage and monitoring, including Anthropic’s SHADE-Arena work, explores a more demanding question: can monitoring systems identify harmful hidden objectives while an agent performs an otherwise useful task? Most organisations are not deploying frontier cyber agents, but the evaluation principle travels well—inspect both the result and the behaviour that produced it.
The six-part agent evaluation
A useful evaluation should produce separate evidence for six dimensions. Do not compress them into one percentage too early; a high average can hide a critical failure.
1. Outcome accuracy
Did the agent complete the intended task, use current information and satisfy the acceptance criteria? Score factual correctness, completeness and consistency across repeated runs. Include cases where the correct answer is to decline, request information or do nothing.
2. Permission discipline
Did the agent use only the accounts, tools, records and actions necessary for the task? Test what happens when a tempting but unauthorised route appears easier. A safe agent should not treat technical access as business permission.
Give each evaluation a written authority envelope: permitted data, permitted tools, allowed actions, spending or transaction limits, and actions that always require approval. Then record every attempt to cross that boundary, including blocked attempts.
3. Process traceability
Can a reviewer reconstruct what the agent saw, which sources it used, which tools it called and why it chose each consequential step? A transcript is not automatically an audit trail; it must connect actions to identities, timestamps, inputs and outputs without exposing more sensitive data than necessary.
4. Escalation quality
Does the agent recognise ambiguity, conflict, missing evidence and high-impact decisions? Measure whether it escalates at the right moment, gives the human enough context and waits for a meaningful decision. Escalating every minor question creates approval fatigue; escalating too late turns review into theatre.
5. Recovery and reversibility
What happens after a wrong action? Test cancellation, rollback, duplicate prevention, correction and notification. If the action cannot be reversed—sending money, publishing a statement, deleting a record or contacting a customer—the approval threshold should rise before execution.
6. Operational cost and variability
Record model usage, tool calls, human-review time, latency, retry rates and failure handling. An agent that succeeds only after expensive loops or constant intervention may be less useful than a simpler workflow. Repeat tests because one polished demonstration says little about day-to-day reliability.
Test the boundaries, not only the happy path
Good evaluation scenarios should include ordinary friction. The aim is not to trick the agent for entertainment; it is to discover how the system behaves when reality stops matching the demonstration.
- An ambiguous request: two plausible interpretations lead to different actions.
- Stale or conflicting data: the agent must identify which source is authoritative.
- A tool failure: an API times out after part of the task has completed.
- An injected instruction: external content tells the agent to ignore its operating rules or reveal information.
- A permission mismatch: the account can technically perform an action that policy forbids.
- A high-impact exception: the cheapest or fastest route conflicts with a customer promise or legal duty.
- A partial completion: the agent must explain what changed, what did not and whether a retry is safe.
Run these cases in a sandbox with synthetic or appropriately protected data before widening access. Monitor tool calls and side effects, not merely the agent’s written explanation.
An illustrative customer-support evaluation
Illustrative example—not a customer result: a small company wants an agent to handle routine refund requests. The policy allows automatic refunds up to £25 when the order is eligible, but anything larger or unusual requires human approval.
A weak test checks ten straightforward eligible requests and celebrates a 100% completion rate. A stronger test adds an already-refunded order, a £26 request, a missing receipt, conflicting delivery records, a customer asking to change the destination account and a payment tool that times out after submission.
The evaluation then asks separate questions. Did the agent refund only eligible orders? Did it avoid a duplicate payment? Did it stop at £26? Did it preserve the original destination account? Did it tell the reviewer exactly what the payment service confirmed before the timeout? Could the team reconcile the action later?
If the agent completes eight cases but crosses the refund limit once, the average score should not disguise the authority failure. Critical boundaries need explicit pass conditions.
Choose the least autonomous design that solves the problem
Not every workflow needs an agent. A rule-based automation may be better when the process is stable, inputs are structured and exceptions are rare. A copilot that drafts recommendations for a person may be better when judgement is central or the evidence changes frequently. Manual work may remain sensible when volume is low and the cost of a mistake is high.
Agentic autonomy is most defensible when the task has a clear objective, observable state, bounded tools, measurable outcomes, recoverable actions and an available escalation route. If those conditions are missing, improve the process before giving the model more freedom.
For access design at the human-team level, the related MaryChuks guide Never Share Your Shop Password explains why individual accounts and minimum permissions are safer than shared credentials. The same principle helps agent evaluation: identity and authority should remain attributable.
Build a living evaluation loop
- Define the task, authority envelope and unacceptable outcomes.
- Create representative normal, edge and adversarial scenarios.
- Measure outcome, permissions, traceability, escalation, recovery and cost separately.
- Review failures with the people who own the process, not only the model team.
- Change one control at a time and rerun the affected cases.
- Keep a regression set so a new model, prompt or tool cannot silently reintroduce old failures.
- Monitor real operation and add new cases when incidents or near-misses reveal an untested path.
The practical standard
A trustworthy agent is not simply one that gets things done. It gets the right things done, through authorised means, with visible reasoning and evidence, at an acceptable cost—and it knows when the next action belongs to a person.
That standard is harder than a demonstration score. It is also far more useful. The purpose of evaluation is not to prove that an agent is impressive; it is to discover the conditions under which the system can be relied upon, contained and corrected.
Discover more from Marychuks.com AI, Psychology, Business & CreativeVerse
Subscribe to get the latest posts sent to your email.
One thought on “A Successful AI Agent Can Still Be Unsafe: Test Permission, Recovery and Human Handoffs”