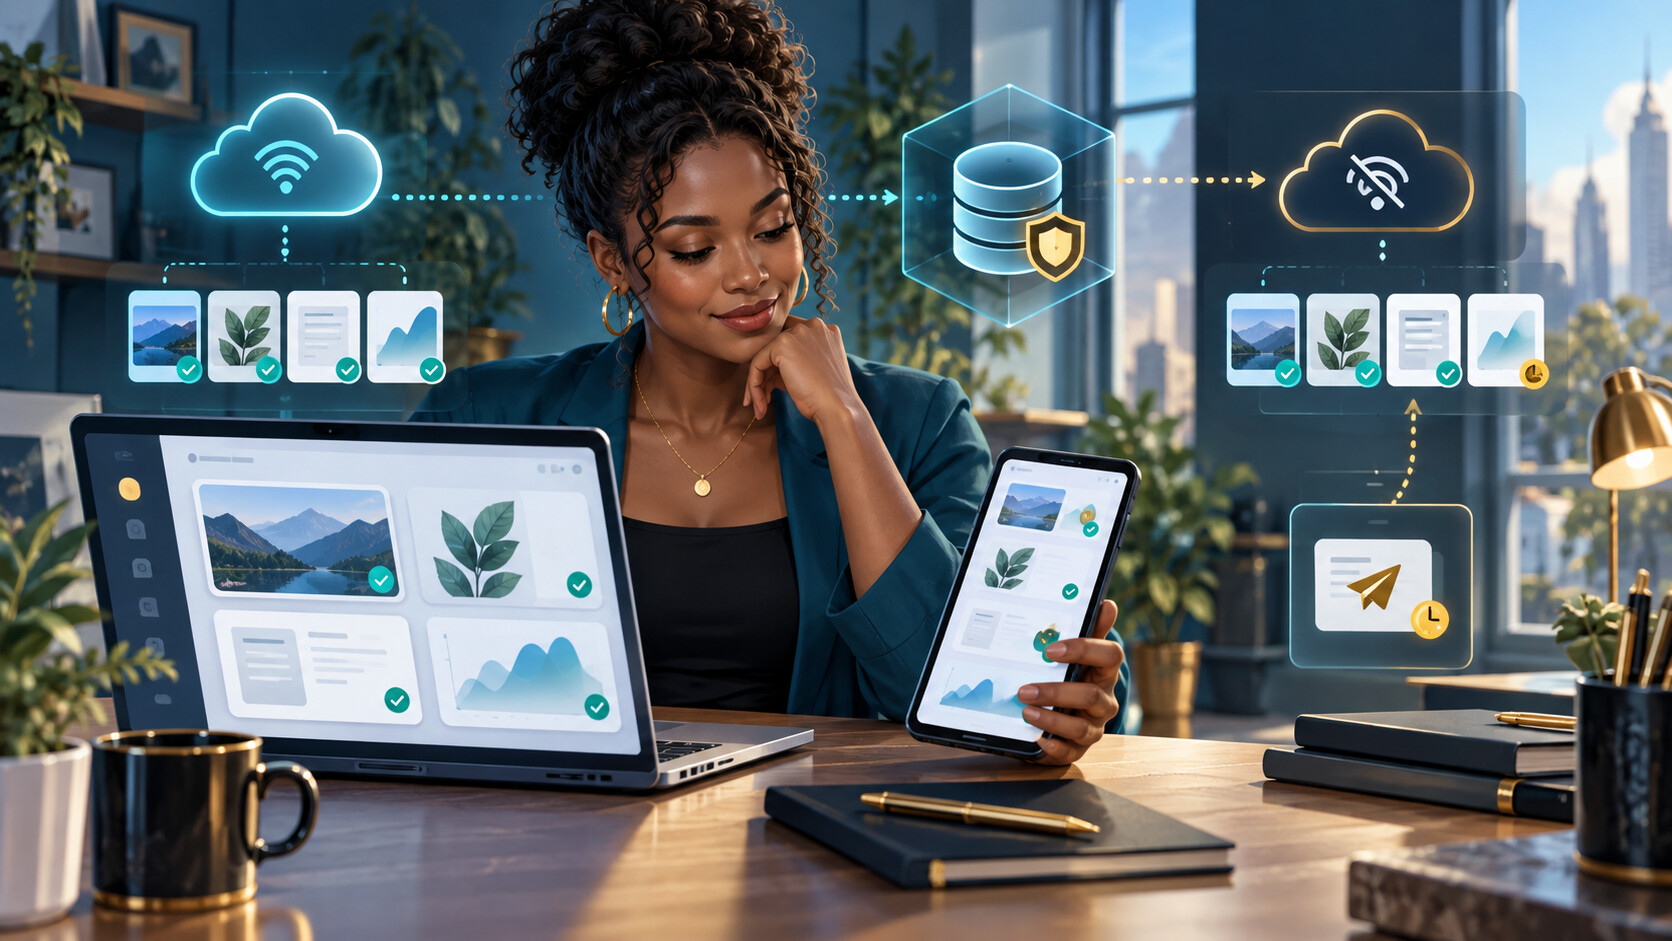
A web app does not become offline-first because its home screen opens without Wi-Fi. Reliability begins when the product team decides which user journeys must survive a broken connection, what data may be stored locally, how actions will be reconciled later and what the interface should say when completion is impossible.
That distinction matters for founders. A superficial cache can create the appearance of resilience while hiding stale prices, duplicated submissions or work that was never saved. A trustworthy offline experience makes explicit promises and keeps them under failure.
Start with the promise, not the service worker
Google’s web.dev guidance describes a service worker as middleware between a Progressive Web App and the servers it uses. Within its scope, it can intercept requests and choose whether to respond from a local cache, a network request or locally generated logic. That is powerful infrastructure, but it does not decide what the product ought to do.
Before writing cache rules, divide the product into three classes:
- Must work offline: previously opened reference material, a saved draft, an itinerary, a ticket already issued or a form the user is actively completing.
- May be queued: messages, uploads or edits that can safely wait and be synchronised later.
- Must require a live connection: actions whose truth depends on current server state, such as taking payment, reserving scarce stock or confirming another user’s latest change.
This is a product decision. The technology implements it. Claiming that everything works offline is usually less credible than defining a small set of important journeys that work predictably.
Not all cached information should behave the same way
A cache-first strategy checks local storage before the network. It can be fast and useful for stable assets, but it increases the chance of returning stale information. A network-first strategy asks the server first and falls back to cached material when the network fails. The better choice depends on the resource.
- Static interface assets: application shell files, icons and stable help content often suit cache-first handling with controlled versioning.
- Frequently changing content: feeds, dashboards and availability data may need network-first behaviour with a visibly dated fallback.
- Private user records: local persistence may improve continuity but requires a deliberate privacy, encryption and sign-out policy.
- Transactions: a stored request is not proof that a booking, payment or order succeeded.
The inference is straightforward: “available offline” is incomplete without freshness and authority. Show when content was last updated, whether it is a local copy and which actions remain pending.
Queue actions without creating duplicate consequences
MDN explains that background synchronisation can allow a service worker to attempt a short task once connectivity returns. It also warns that browsers may stop service workers and that retry behaviour is constrained. Background execution is an opportunity, not a guarantee of uninterrupted processing.
A robust queue therefore needs more than “retry later”. Each action should have a stable identifier, an explicit status and server-side protection against accidental repetition. If a user taps “send” twice while the interface is uncertain, the system should not silently create two orders or messages.
- Mark the item as waiting to send, not sent.
- Let the user inspect, cancel or retry a pending item where appropriate.
- Use idempotency or equivalent server logic for operations that must not be applied twice.
- Define what happens when the server rejects an old action because the underlying record changed.
Design conflict as a normal state
Suppose two people edit the same record while one is offline. When that device reconnects, “last write wins” may erase valid work. There is no universal answer: a shopping list may merge safely, while a legal document or stock count may demand review.
Choose a conflict policy for each data type:
- Reject and explain: preserve the local draft but ask the user to review the newer server version.
- Merge automatically: suitable only when independent changes can be combined without ambiguity.
- Preserve both: create a recoverable copy rather than discarding either version.
- Use authoritative server state: appropriate where regulation, inventory or payments make local data non-authoritative.
The interface should say which rule was applied. Silent conflict resolution is convenient until it destroys something valuable.
Treat the first visit as a special case
A service worker does not control the initial page request before it has been registered and activated. web.dev also recommends treating it as an optional enhancement because support and lifecycle conditions vary. This means the app’s core first-run experience must still fail sensibly without relying on a pre-existing cache.
Do not test only on a developer’s device that has opened the application dozens of times. Test a clean browser profile, a first visit on a weak connection, an update with an older worker still active and a return after cached data has expired.
A six-part offline reliability test
- Cold start: open the app for the first time with a slow connection. Does it communicate progress and failure clearly?
- Sudden loss: disconnect midway through an edit or upload. Is the user’s work retained?
- Long absence: return after days offline. Is cached information dated and labelled?
- Reconnect: restore the network. Are queued actions synchronised once, with visible outcomes?
- Conflict: change the same record elsewhere before reconnecting. Does the chosen conflict policy protect meaning?
- Update: deploy a new application version. Can users move from old cached assets without a broken hybrid interface?
The smallest credible offline-first release
For an early-stage product, the strongest first release may be modest:
- the application shell loads reliably;
- one essential reading or drafting journey continues offline;
- pending actions are clearly labelled and recoverable;
- stale content shows its last successful update;
- sensitive and authoritative actions refuse safely when a live check is required.
This is not less ambitious than caching the entire interface. It is more honest. Reliability is experienced at the moment a connection disappears, an update collides or a retry occurs. The product earns trust by making those moments understandable.
The critical takeaway
Service workers, caches and background APIs provide mechanisms. They do not provide a reliability policy. Offline-first succeeds when product rules, interface language, local storage, server reconciliation and failure testing agree about what the user can safely expect.
Build the promise first. Then cache only what helps you keep it.
Primary and technical sources
- W3C: Service Workers specification (living technical specification; accessed 20 September 2026).
- web.dev: Service workers (Google-maintained PWA guidance; accessed 20 September 2026).
- MDN: Offline and background operation (technical guidance; accessed 20 September 2026).
Discover more from Marychuks.com AI, Psychology, Business & CreativeVerse
Subscribe to get the latest posts sent to your email.